Shared AI training control is a proposed cross-provider signal that websites can place in robots.txt to express whether their content may be used for generative AI model training. Google announced on 30 October 2026 that it plans to support the new policy token in early 2027.
This is a website-governance decision, not a quick SEO setting. Publishers should first separate training preferences from crawling, indexing and AI-powered Search visibility, then confirm who has authority to decide. The technical implementation is simple; the commercial and rights implications need more care.
Current status: Google has announced planned support, while the underlying industry specification remains work in progress. Do not present the token as universally supported or as a legal enforcement mechanism.
What Google announced
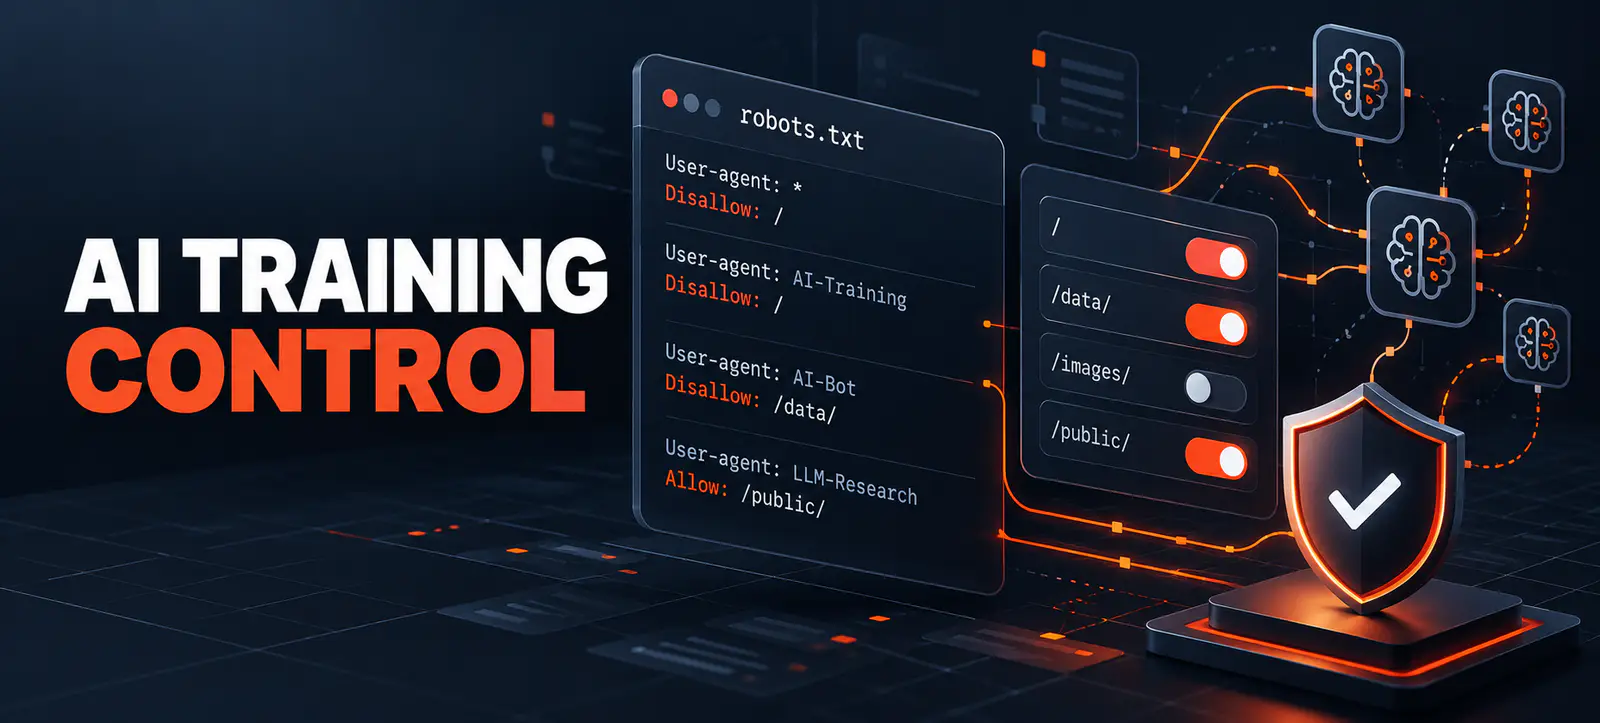
Google’s shared AI training control announcement says participating providers will be able to interpret a common policy token in robots.txt. A website can express a broad training preference once instead of maintaining only provider-specific instructions.
The token is __usage_ai-training. Google says that when a site disallows this shared token and does not explicitly specify Google-Extended, it plans to interpret the rule as if Google-Extended were disallowed. Google also says sites can retain provider-specific instructions where they need a different decision.
Understand the four separate controls
Control
Primary purpose
Does it block Google Search?
Decision owner
Googlebot robots.txt rules
Manage crawler access to specified paths
Can affect crawling and discovery
SEO and engineering
Robots meta noindex
Request that an accessible page not appear in Search
Yes, when Google can crawl and see it
SEO and content owner
Google-Extended
Control specified Gemini training and grounding uses
No, according to Google
Rights, legal and digital owner
Shared AI training token
Express a broad training preference to participating providers
Not designed as a Search-indexing control
Rights, legal and digital owner
AI Search participation control
Manage participation in specified generative Search features
Affects covered AI Search experiences, not ordinary Search
SEO and business owner
These settings should not be substituted for one another. Kayaar’s Google AI Search opt-out guide explains the separate visibility and traffic decision for AI Overviews, AI Mode and related Search experiences.
How the policy token is expected to look
Google’s updated Google-Extended documentation gives the planned token and says support is intended for early 2027. A broad preference against training would use a robots.txt group such as:
User-agent: __usage_ai-training
Disallow: /
The policy token is not a separate crawler identity making HTTP requests. It uses familiar robots.txt grouping and path rules to communicate a content-use preference. A provider that does not recognise the token may ignore that group, so coverage depends on documented adoption.
Decide the desired outcome first
Inventory the content and rights involved. Separate owned editorial material, licensed images, customer uploads, public documentation, product data, press assets and pages already governed by contracts. The organisation may reach different decisions for different folders.
Ask what the preference should protect, which uses are acceptable and what business value might be affected. Include editorial, product, legal, licensing, engineering and SEO stakeholders. Record the decision-maker and the evidence used; do not let a developer infer rights policy from a ticket title.
Audit existing robots.txt rules
Download the live robots.txt file, identify every user-agent group and map important allow and disallow rules. Look for duplicate groups, wildcards, conflicting path patterns and provider-specific AI controls. Confirm the file served on each hostname, because subdomains can have different policies.
Do not edit a production file without understanding its existing crawl role. Kayaar’s technical SEO audit guide explains how to document affected URL sets, business impact, approval and post-release validation.
Plan precedence explicitly
Google says publisher-specific controls can coexist with the shared signal. That enables a broad default with a different Google-Extended choice, but it also creates room for accidental contradictions. Write a matrix showing the intended shared preference, every proprietary token and the paths each rule covers.
For Google, the announced default matters: a shared training disallow will be treated like a Google-Extended disallow when Google-Extended is absent. If the organisation wants another outcome for Google, it should document and test the explicit rule rather than assume precedence.
Test without confusing crawling and use
Validate syntax, file availability and path matching in a staging review, then deploy through the normal change process. Save the before-and-after file, timestamp, owner and rollback. Check that important Googlebot crawling rules remain unchanged and that the file stays publicly accessible.
A successful fetch does not prove that every provider honours a usage preference. Monitor vendor documentation and implementation dates. Avoid judging the change through rankings: Google says Google-Extended does not affect Search inclusion or act as a Search ranking signal.
Protect non-search content separately
Robots.txt is public and should not be used to secure confidential information. Authentication and access controls remain necessary for private material. For public pages that should not appear in Search, use the appropriate indexing control rather than assuming a training preference will remove them.
The user-generated spam prevention guide shows why link-shared pages, public tools and user-created outputs need an intentional index policy. Training preference, abuse prevention and search eligibility are related governance tasks but separate technical controls.
Maintain a change register
Record the approved preference, scope, rule text, stakeholder sign-off, effective date and review date. Revisit it when contracts, licensing, publishing models or provider documentation change. Subscribe to first-party changelogs rather than relying on screenshots or copied examples.
Also review the content-production side. Kayaar’s Google generative AI content guidance explains how to maintain accuracy, originality and user value when AI assists publishing, regardless of the training policy chosen for the resulting pages.
Final readiness checklist
Content ownership and licensing have been mapped.
Training, crawling, indexing and AI Search controls are distinguished.
The shared preference and provider-specific exceptions are documented.
Robots.txt groups and path matching have been reviewed.
Approvers, deployment owner and rollback are recorded.
Implementation waits for confirmed support and current documentation.
Shared AI training control may reduce duplicated instructions across providers, but it does not remove the need for an explicit rights policy. Prepare the governance and technical inventory now, then implement only against confirmed specifications. For a site-specific review, contact Kayaar.
FAQs
What is the shared AI training control?
It is a cross-provider robots.txt policy token intended to let websites express a broad preference about generative AI model training.
When will Google support the shared training token?
Google says it intends to support the __usage_ai-training token in early 2027, so publishers should confirm current documentation before deployment.
Does the token remove pages from Google Search?
No. It expresses a training-use preference and is not an indexing control. Crawling, noindex and AI Search participation require separate decisions.
Is the shared token the same as Google-Extended?
No. The shared token is cross-provider, while Google-Extended is Google-specific. Google has documented how it plans to interpret both together.
Should every publisher block AI training?
No universal answer applies. The decision should reflect content rights, licensing, business value, stakeholder policy and applicable legal advice.