A Google Ads test is not automatically a useful experiment. Changing bids, audiences, creative and landing pages together may produce movement, but it rarely explains what caused it. A weak process can also expose a Dubai business to uncontrolled spend, distorted lead quality and permanent campaign changes based on incomplete evidence.
Before appointing a Google Ads expert in Dubai, ask how experiments are proposed, approved, isolated, monitored and applied. This governance checklist helps a buyer distinguish disciplined testing from routine optimisation presented as proof.
Start with a decision, not a feature. Every experiment should state what the business will do if the result is positive, negative or inconclusive. If no decision changes, the test may not justify its cost or operational risk.
1. Define the commercial decision
Write one test question in plain language. Examples include whether a new offer improves qualified enquiries, whether a bidding target protects margin, or whether a landing-page route increases completed applications. Name the account, campaigns, market, products and decision owner.
Choose one primary business outcome before launch. Click-through rate can diagnose creative response, but it does not prove lead value or profit. If sales quality is uncertain, use Kayaar’s lead-quality review checklist to define the downstream stage that matters.
2. Confirm the baseline is trustworthy
Record the control campaign’s recent budget, targeting, conversion actions, values, attribution settings, lead lag and seasonal context. Verify that tracking fires correctly and that the landing page, CRM route and sales response process will remain available throughout the test.
Do not launch during a broken measurement period or an operational event that affects only one arm. Review search terms, network settings and exclusions first. Kayaar’s waste-reduction audit helps separate obvious account defects from questions that genuinely need an experiment.
3. Isolate the variable and hypothesis
State the change, expected direction and reason. A useful hypothesis might predict that a clearer value proposition will increase qualified conversion rate without raising cost per qualified lead beyond an agreed ceiling. Avoid broad claims such as “automation will improve performance.”
Change as little as practical between control and treatment. Multiple changes can be tested as a package when that package is the actual decision, but the team should not pretend the result proves which component worked. Log other account activity that might contaminate comparison.
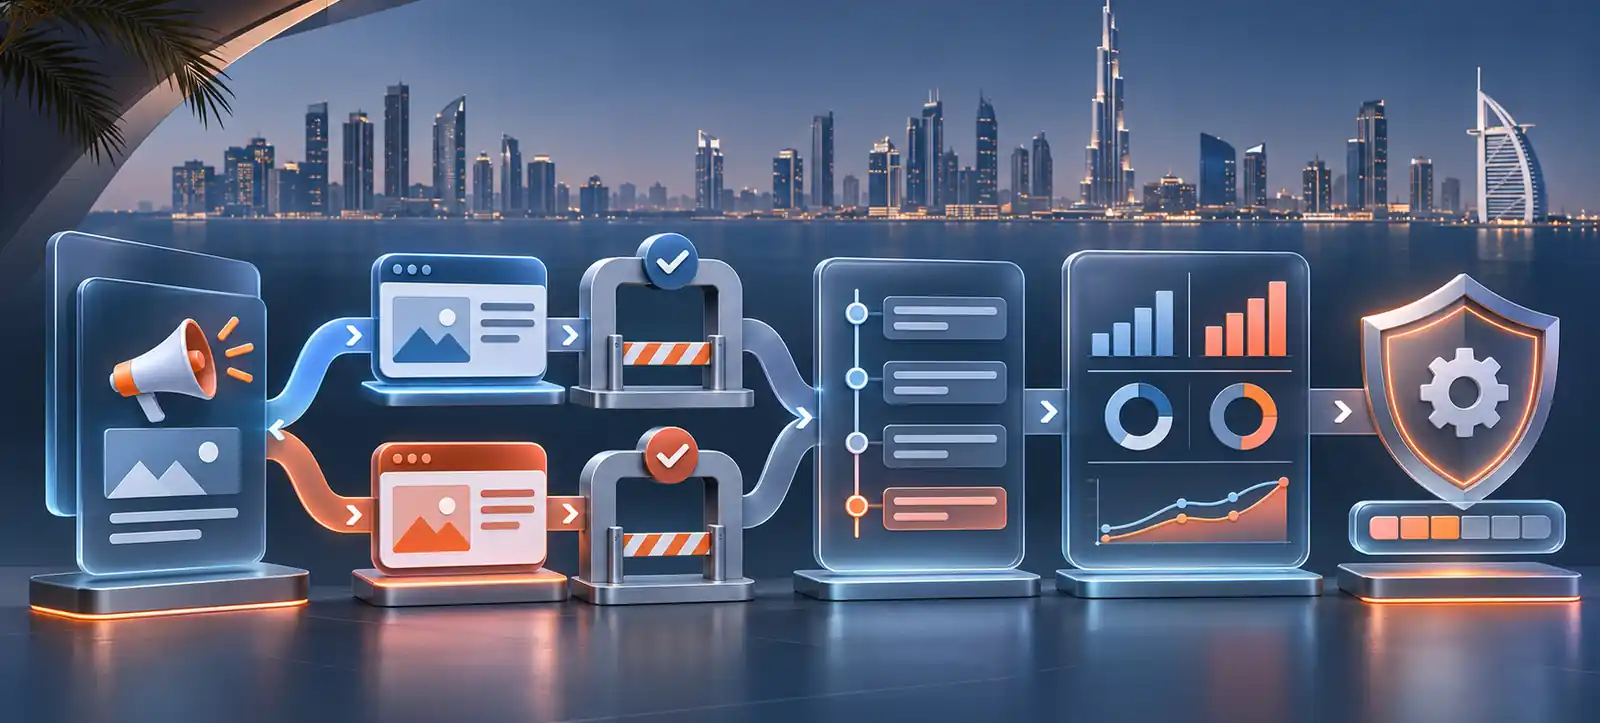
4. Approve the test through fixed gates
Gate
Evidence required
Decision owner
Stop condition
Business case
Decision, hypothesis and expected value
Marketing or commercial lead
No action depends on the result
Measurement
Primary metric, guardrails and data source
Analytics owner
Tracking or CRM stages are unreliable
Exposure
Campaigns, dates, split and spend limit
Budget owner
Risk exceeds the approved ceiling
Operations
Landing page, stock and sales readiness
Business owner
Capacity cannot support treatment demand
Rollout
Success rule, review date and rollback plan
Named approver
No agreed route for each outcome
5. Configure exposure deliberately
Google describes its Experiment Center as a hub for comparing campaign settings, assets or strategies and for lift studies that estimate incremental impact. The available method depends on campaign eligibility and the business question, so the expert should explain why the selected experiment type fits.
Document start and end dates, eligible campaigns, traffic or budget treatment, conversion goals and any auto-apply choice. Estimate the acceptable spend before the test, not after seeing early results. For AI Max-specific decisions, compare the controls with Kayaar’s AI Max experiment guide.
6. Protect the test with change control
Freeze unrelated edits where practical. Urgent changes should require a ticket that records the reason, operator, timestamp, affected entities and expected impact on interpretation. Set escalation thresholds for overspend, tracking failure, disapproved ads, broken pages and sharp deterioration in qualified outcomes.
Google Ads change history lists account, campaign and ad-group changes from the past two years and can identify interface users or indicate API and system activity. Use it as platform evidence, but maintain a business decision log because the account record does not explain every approval or commercial reason.
7. Read the result against pre-agreed rules
Review the primary metric and guardrails together. A lower acquisition cost is not a win if lead acceptance, revenue, margin or geographic fit deteriorates. Segment only where the sample and decision justify it; repeated slicing can create a persuasive story from noise.
Classify the outcome as adopt, reject, continue, redesign or inconclusive. Record confidence, materiality, data limitations and operational events. Use Kayaar’s Google Ads measurement stack guide to distinguish attribution reporting from incrementality and broader business measurement.
8. Apply winners through a controlled rollout
Approval to apply a result should name the settings, campaigns, rollout date, budget, monitoring window and rollback trigger. Preserve screenshots or exports of the control, treatment, scorecard and decision. Do not turn a limited result into an account-wide rule without checking whether markets, products and audiences are comparable.
Monitor after application because auction conditions, learning behaviour and volume can change at full exposure. If performance breaches a guardrail, pause the rollout and investigate rather than defending the original conclusion.
9. Evaluate the expert’s operating discipline
Ask for a sample test register showing hypotheses, approvals, live status, spend, results and decisions. The register should include failed and inconclusive tests, not only wins. Confirm who can create experiments, alter budgets, apply results and close tests.
Put these duties into the engagement scope. Kayaar’s contract and fee review checklist helps connect access, change control, evidence ownership and exit continuity to the commercial agreement.
A credible expert treats experiments as governed investments. Clear decisions, reliable baselines, limited variables, recorded approvals and controlled rollout make learning useful even when a treatment does not win.
FAQs
How many variables should a Google Ads experiment test?
Test one material variable when you need to identify its effect. A package of changes can be valid when the package itself is the business decision, but the result cannot prove which component caused the outcome.
Should an expert apply a winning experiment immediately?
No. Confirm the success rule, guardrails, data quality and operational context first. Approve a defined rollout with a monitoring window and rollback trigger rather than applying the result across unrelated campaigns automatically.
What should stop an experiment early?
Pre-agreed triggers may include tracking failure, uncontrolled spend, broken landing pages, policy disapprovals, inventory problems or serious deterioration in qualified outcomes. Avoid stopping only because early results look disappointing.
Is Google Ads change history enough for governance?
No. It provides useful platform evidence about many changes and operators, but a separate decision log should record the hypothesis, approval, commercial reason, exception and interpretation.
What should a campaign experiment register include?
Include the owner, hypothesis, control, treatment, dates, exposure, primary metric, guardrails, spend limit, approvals, incidents, result, decision and rollout status. Retain failed and inconclusive tests as well as winners.